

AI Hallucinations are Part of Dreams not Bugs
Anime & AI News
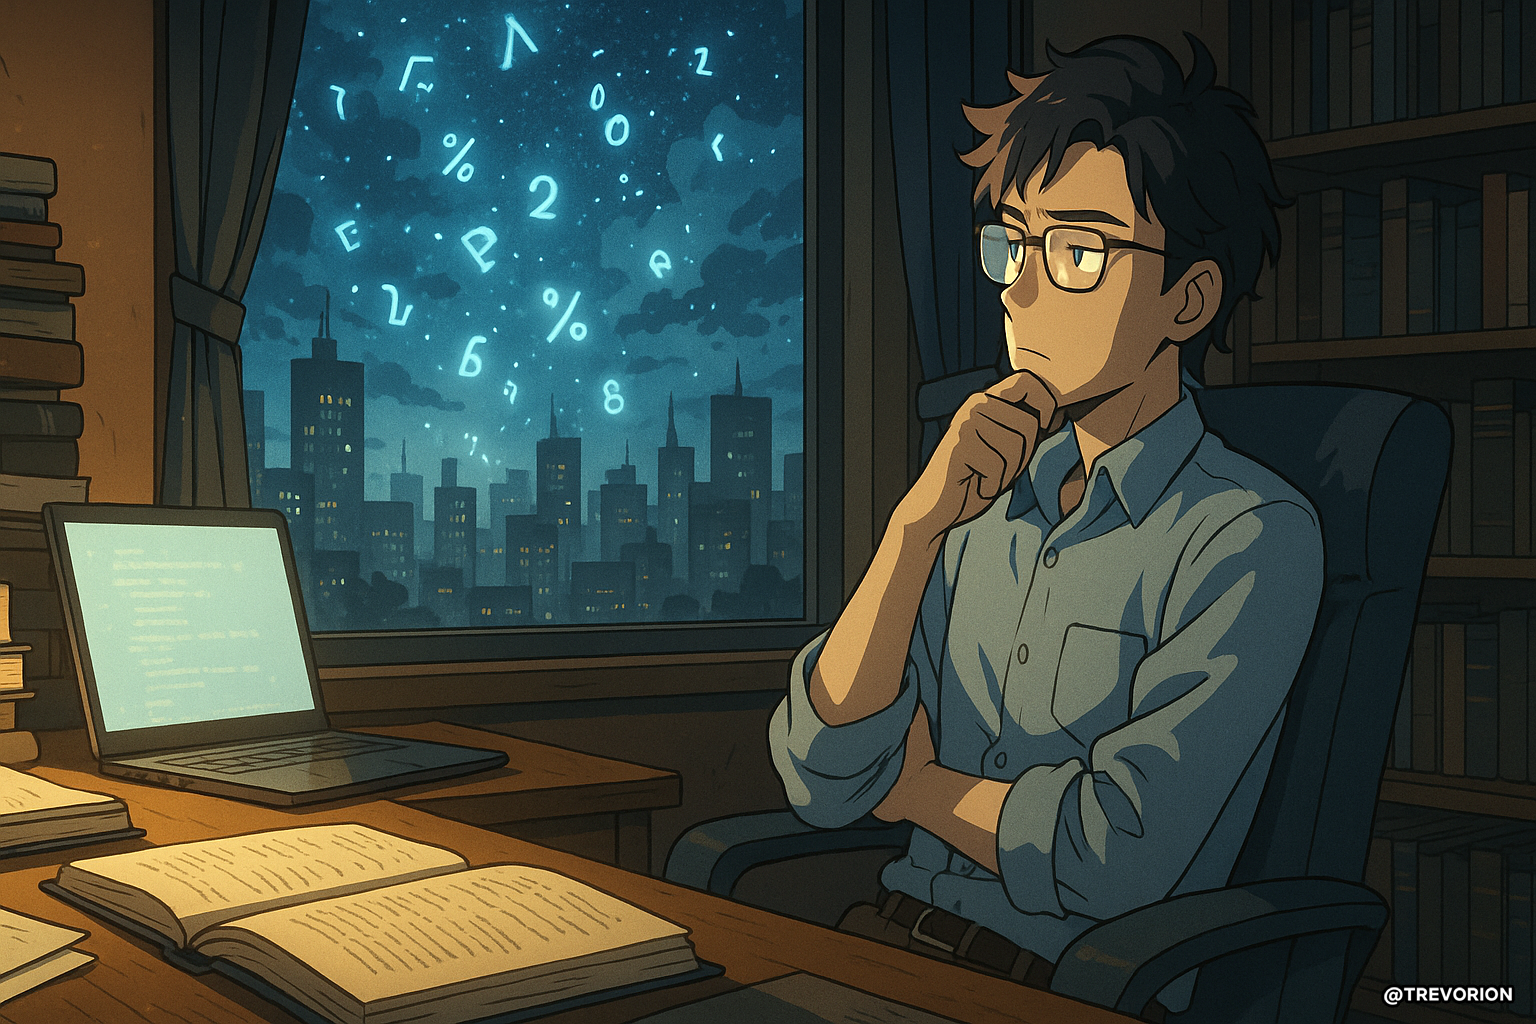
Hallucinations in large language models (LLMs) are not glitches but a byproduct of how they’re trained and evaluated. During pre-training, models learn to predict the next word, rather than verifying facts, making confident guesses inevitable. Fine-tuning and reinforcement learning often reinforce this behavior, as evaluators reward confident answers, even if they are incorrect. OpenAI argues the issue lies in evaluation: current benchmarks reward accuracy but penalize abstaining, encouraging risky guesses. They propose rewarding honesty when a model admits to uncertainty, potentially reducing harmful errors in high-stakes areas such as law or government. This challenges the assumption that progress requires ever-larger models and massive compute. Instead, better evaluation and training methods may be more critical. Trust, ultimately, depends on user awareness and responsibility.
Medium, Generative AI, Andrea Rosales – AI Hallucinations Are Not a Bug But a Feature – 12th September 2025